An assistant reports that a tool failed and immediately tries again. Sometimes that helps. Sometimes it repeats the same invalid request, makes a permission problem noisier or creates uncertainty about whether an action already happened.
A useful error policy begins with a question: what evidence do we have about the failure? “Tool error” is too broad to decide the next step. Separate the request, the authorization, the service and the result before giving an assistant permission to retry.
Identify the layer that failed
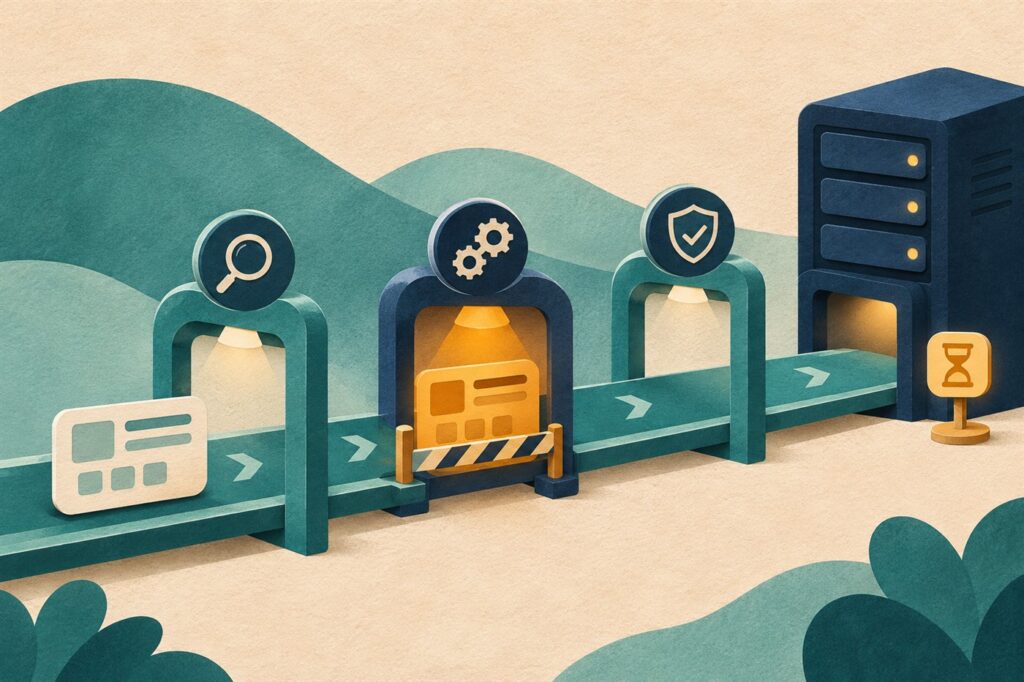
At the input layer, a request might contain a missing field, an unsupported value or the wrong identifier. At the access layer, the current account may lack permission. At the service layer, the destination might be unavailable. At the result layer, the call may succeed technically but return information that does not satisfy the task.
These are editorial diagnostic categories, not a universal error taxonomy. A connector can wrap an underlying failure in its own message, and some tools do not use HTTP at all. Start with that tool’s documented error contract and the actual response.
Read a status code without overreading it
For HTTP-based tools, RFC 9110 defines 400 as a perceived client error, 401 as missing valid authentication credentials, 403 as a refusal to fulfill the request, and 503 as temporary inability to handle it. These signals help narrow an investigation; they do not by themselves identify which field, account policy or dependency caused your failure.
RFC 6585 defines 429 for too many requests and allows a Retry-After field. Consult the service’s own guidance about limits and waiting. An error message is evidence to interpret, not permission to bypass a restriction.
A fictional document lookup
Suppose an assistant is asked to summarize a project document. Its lookup fails because it supplied a display title where the tool requires a document ID. Repeating the title will not resolve that mismatch. The next step is to obtain the appropriate identifier through the authorized document list, then make a corrected lookup.
Change the scenario: the same valid lookup now returns a service-unavailable response. Rewriting the document ID is not supported by that evidence. A bounded wait and retry may be appropriate under the service’s guidance, with a clear stopping point.
In a third version, the lookup returns an empty result. That may be a successful search with no matches. It does not prove that the document never existed, nor that there is an outage. Check the search scope, filters and account access before drawing a conclusion.
Use a compact decision record
| Observed evidence | Reasonable next check | Avoid |
|---|---|---|
| Named argument is invalid | Compare it with the tool’s accepted input | Retrying unchanged |
| Access is refused | Confirm the authorized account and scope | Seeking broader access automatically |
| Temporary service failure | Check retry guidance and a bounded retry policy | An unlimited loop |
| No matching result | Inspect query scope and filters | Inventing the missing information |
| Write request timed out | Inspect whether the intended change exists | Assuming nothing happened |
Be more careful when a tool changes something
A failed read usually leaves a different recovery problem from an uncertain write. If a message send or record creation times out, the destination may still have completed it. Check an authoritative receipt or the destination’s visible state before repeating the action. Use a service’s documented duplicate-prevention mechanism when one exists; do not assume every tool provides one.
Set the recovery rule before deployment: which operations may retry, under what conditions, how many attempts are allowed, and when a person must review the state. The agent evaluation scorecard can help organize a broader review, but a passing task example does not replace a recovery policy.
Log enough to learn, without copying secrets
Keep the operation name, time, safe error category, attempt count and confirmed outcome. Do not paste passwords, access tokens or private document contents into a general troubleshooting log. Record the smallest useful evidence in the appropriate approved system.
For structured arguments, also read Valid JSON Can Still Be Wrong. If recovery leaves the answer unresolved, use the uncertainty guide to keep that uncertainty visible. A clear stop with an accurate explanation is more useful than an apparently successful answer built on an unverified retry.
AI-generated conceptual illustration. Examples and the diagnostic worksheet are editorial proposals; no service outage experiment was performed.