Catch-up edition for the October 27 editorial slot. First published November 2, 2026.
Your assistant keeps giving the wrong answer about a return policy. Should you connect a document library or fine-tune a model? Before choosing either, find out what went wrong. The assistant may have lacked the current policy, retrieved the wrong version, misunderstood the question or ignored a formatting requirement. Those are different problems.
Start with a few failed tasks and the result you expected. An architecture diagram is easier to draw once that small evidence set exists.
Information and behavior are different starting points
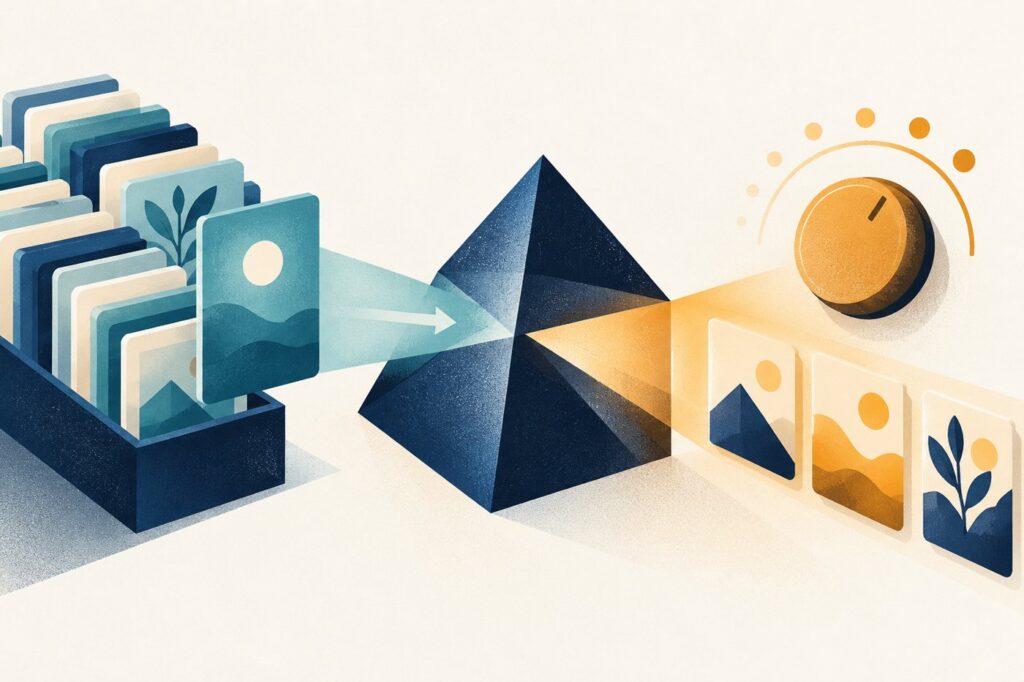
Retrieval-augmented generation brings selected material into the context used to produce an answer. Fine-tuning changes a model through additional training examples. AWS’s comparison of retrieval and fine-tuning describes the approaches and the possibility of combining them. Neither name, by itself, tells you whether a proposed implementation will solve your task.
For frequently changing facts, a maintained information source is often the first thing to examine. For a stable task that repeatedly demands a particular response pattern, training examples may be relevant. These are starting hypotheses to test, not a rule that retrieval handles all facts or training handles all behavior.
Write the failure in one sentence
“The answer was bad” is too broad to guide a change. Prefer “the answer used last year’s return window” or “the answer contained the right facts but omitted the required escalation field.” Keep the source, expected result and observed result together.
| Observed problem | First check | Possible next experiment |
|---|---|---|
| Current fact missing | Was the authoritative source available? | Supply the relevant passage explicitly |
| Old fact repeated | Did retrieval select an obsolete version? | Repair version selection and test again |
| Format inconsistent | Is the output contract clear and enforced? | Try examples and schema validation |
| Reasoning wrong despite correct context | Did the model connect the facts correctly? | Test a clearer task decomposition or another model |
A policy example that separates the layers
Consider a fictional retailer. Its current policy gives unopened items a 30-day return window. An older document says 14 days. The assistant answers 14 days and supplies a link to the archive. In that case, adding more examples of friendly customer-service language would not repair the obsolete source selection.
Now change the failure: the assistant correctly says 30 days but sends the message without the approval required by the workflow. Better retrieval would not grant or enforce that approval. The application needs an action boundary outside the generated text.
Both examples concern the same business topic. They point to different repairs because the actual failure is different.
Try the smallest informative experiment
Take a representative failed question and provide the correct source passage directly. Keep the requested output and evaluation rule fixed. If the answer improves, you have evidence that access to information mattered in that example. You have not yet proved that a retrieval system will consistently find the right passage.
Next, test the retrieval step separately: inspect which documents and passages it returns. Include old versions, similar product names and questions the library cannot answer. For a training experiment, keep examples used to evaluate the result separate from examples used to train it. A model repeating familiar training cases is not enough evidence of useful generalization.
Budget for maintenance, not just setup
A document pipeline needs ownership of ingestion, permissions, updates and removal. A customized model needs suitable training data, evaluation and a plan for later changes. Both approaches still require review of incorrect or unsupported outputs. Do not compare only the initial implementation effort.
Write down the person responsible for correcting a source, changing an example and approving a release. If nobody owns those tasks, the system can become stale regardless of which architecture you choose.
Make the decision traceable
Record the failure category, experiment, result and next action. The task scorecard offers a place to track evidence and permissions. If the problem is a well-formed but false record, read why valid JSON is not a truth check. Choose the intervention that addresses the observed failure, then test whether it actually did.
AI-generated conceptual illustration. The retailer and policy examples are fictional.